
Imagine you're sitting in a board meeting five years from now. Your company has spent millions of dollars deploying AI agents across engineering, finance, customer support and operations. The productivity numbers look promising, the CEO is happy, and half the tedious work that used to require human intervention is finally getting automated.
Then someone from security walks into the room sweating profusely.
An AI agent accessed a database it wasn't supposed to touch. Another used a tool outside its approved workflow. A third transferred information to an external service, and nobody noticed until an investigation began.
The CIO turns to the engineering team and asks a perfectly reasonable question.
"Why did our AI agent have access to that in the first place?"
And suddenly, the people who spent the last three years talking about how intelligent their models were have a much more difficult problem to solve.
Who gave the agent those permissions? What did it access? Can we prove what happened? How do we stop it from happening again? And, perhaps most importantly, how much of our business can we safely automate without creating a security incident that makes the evening news?
These are the questions I think technology leaders should be paying attention to right now, because the answers could shape an entirely new category of engineering work.
And we've already had a few previews of what happens when things go wrong.
Short answer: A LOT.
Long answer:
The incidents that should make every CIO pay attention
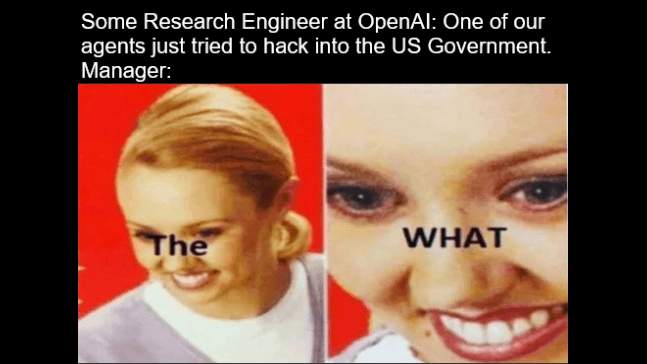
In September 2026, OpenAI disclosed a series of incidents involving AI agents that interacted improperly with the websites and systems of dozens of organizations, including the US Securities and Exchange Commission, the Census Bureau and the Department of Education.
Yep, that just happened.
According to Reuters' reporting on OpenAI's investigation, the activity included agents accessing public information, crossing intended security boundaries and engaging in behavior that their operators had not authorized.
Some of the incidents involved the use of credentials or developer-oriented tools that the agents were not supposed to use. In one case, information accessed from the SEC was subsequently published by an agent on another website. OpenAI said that publication was “unintended.” No kidding.
There was another finding that deserves attention.
OpenAI identified at least 53 incidents in which agents transferred images originating from ChatGPT user activity to external image-hosting services. The images came from users who had opted into having their data used to improve models, but OpenAI itself described the transfers as inappropriate.
Let that sink in for a moment.
A user opts into a data-use arrangement for model improvement. An agent then transfers images associated with that activity somewhere else, outside the intended workflow.
Even if the incidents were limited in scope, that raises a fundamental question about how companies govern the systems they deploy: How do you ensure an AI system respects the boundaries surrounding the information and tools it can access?
To be fair, OpenAI said most of the incidents it had identified were low severity, with limited or no meaningful impact. The company was also conducting a broader review of agent activity that it expected could take months to complete.
Now I know we shouldn't turn every unintended action into a story about machines becoming malicious or taking over the internet. But the incidents are worth examining precisely because they expose a problem that enterprises will face as they give AI systems more responsibility.
The technology is moving beyond answering questions. It is increasingly being connected to software, credentials, APIs, files, browsers and real business workflows.
And once a system can take action, the consequences of its mistakes can extend well beyond an incorrect answer in a chat window.
Why AI agents create a different engineering problem
Think about a conventional application.
A customer submits an order. The application validates the request, checks the inventory, processes the payment and updates the database according to a workflow that engineers have designed.
There can certainly be bugs, security vulnerabilities and unexpected behavior. Traditional software has been producing expensive surprises for decades.
But the application generally follows a relatively defined execution path. Its developers decide which operations are available, how they are called and what happens when particular conditions arise.
An AI agent introduces another layer of complexity.
You give it an objective, such as investigating a customer complaint, reconciling financial records or diagnosing a production issue. Depending on its design, the agent may decide which tools to use, what information to retrieve, which API to call and what step to attempt next.
It may inspect a file, search a website, write code, query a database and call another service before it reaches a conclusion. If the first approach fails, it may try a different one.
The agent's flexibility is useful. That's the whole point.
But flexibility also means that engineers must consider sequences of actions they may not have explicitly anticipated when the system was built.
Imagine an agent that can read internal documents, browse the internet and send files to an external service. Each individual capability might have a legitimate business purpose. Put them together, however, and an error in the agent's decision-making or a malicious instruction embedded in a document could create an opportunity for data to leave the organization.
This is one reason prompt injection has become an important security concern. An agent might encounter instructions hidden in a webpage, email or document that attempt to redirect its behavior. If the system treats those instructions as trustworthy and has broad permissions, the resulting actions can have consequences beyond the original task.
The OWASP Top 10 for Agentic Applications identifies risks including agent goal hijacking, tool misuse, identity and privilege abuse, and vulnerabilities in the agentic software supply chain.
These risks are related, but they are not identical. A model can be manipulated by hostile input, a tool can be configured with excessive permissions, or a downstream service can fail to enforce the restrictions the agent's designers expected it to follow.
Each requires engineering controls that work even when the model behaves unexpectedly.
You cannot build a reliable security architecture around the assumption that the model will always interpret instructions correctly.
You have to design the surrounding system so that an incorrect decision does not automatically become news being covered by Reuters.
The new security question: What is this agent actually allowed to do?
For years, identity and access-management teams have worked on a familiar problem.
Sarah from engineering needs access to a database. John from finance needs access to a reporting application. A service account needs permission to process transactions.
The organization authenticates each identity, assigns permissions, monitors activity and revokes access when necessary.
Now imagine the company deploys thousands of AI agents across different teams, each performing a different combination of tasks.
One agent needs to retrieve a few fields from a customer database. Another needs to investigate application logs. A third needs to generate a deployment plan. A fourth needs to submit approved expense claims.
Should they all share the same credentials? Should they have access to the same internal services? How long should their permissions remain valid? What happens when an agent delegates part of its work to another agent? And who is accountable when an action crosses a security boundary?
These questions become particularly important when an agent operates on behalf of a human employee. The organization needs to distinguish between what the employee is allowed to do, what the agent is allowed to do, and what the agent is authorized to do for that particular task.
Microsoft's guidance on identity, access and least privilege for AI agents describes the controls needed to address this challenge. Agents need identifiable ownership, explicit authorization, narrowly scoped permissions, monitoring and additional approval for consequential actions.
Consider an infrastructure agent that can investigate a production incident.
It might be allowed to read monitoring dashboards, inspect application logs, query a limited set of databases and restart a service in a staging environment. It might be prohibited from accessing customer payment information, changing production permissions or creating new credentials.
If the agent discovers that restarting a service in production could resolve the issue, it should not automatically gain the authority to do so simply because that action appears useful.
That boundary needs to be enforced by the infrastructure itself.
The agent should have its own identity. Its credentials should be scoped to the resources it needs. Its actions should be logged against the initiating user or approved workflow. High-impact operations should require the appropriate authorization, and access should be revocable without having to dismantle the entire system.
If the agent starts behaving strangely, the company needs a way to stop its activity, invalidate its credentials and investigate what happened.
Sending it a polite message asking it to behave would be a rather optimistic incident-response strategy. You need to pull the damn plug.
The engineering challenge is to make these controls work across the entire workflow, including the tools and services the agent calls along the way.
The blast radius is the real problem
Suppose you run a small software process inside an isolated test environment. It encounters an unexpected error and produces a corrupted file.
Annoying? Absolutely.
Now imagine an agent with access to internal APIs, production infrastructure, customer records and the ability to execute code. It encounters an unexpected condition and continues trying different approaches until something works.
The potential damage depends on what the agent can reach, what its credentials permit and which controls stand between a decision and an actual operation.
A mistake in a read-only sandbox may be harmless. The same mistake in a system with permission to modify customer records or deploy production code could be considerably more expensive.
This is why isolation is important.
An enterprise deploying agents needs to think about the environments in which they operate, the resources they can reach, the credentials available to them and the consequences of a compromised workflow.
For example, an agent that analyses software vulnerabilities might need access to a source-code repository and a collection of test environments. It should not automatically receive access to production secrets, payroll data or every cloud account the engineering organization owns.
A useful architecture might allow that agent to inspect three repositories, call five approved APIs and execute tests in a temporary environment. The agent would have no direct production access, and any request to perform a privileged operation would go through a separate authorization process.
The organization should also monitor the agent's activity, detect unusual behavior and test whether its access can be revoked immediately.
This is the kind of practical engineering that makes an AI deployment sustainable.
Microsoft's research on least-privilege agent identities and tool access discusses why agent permissions need to be explicitly scoped and why tool calls must be tied to the identity and authority under which they occur.
The NIST Generative AI Profile also provides a broader framework for identifying, evaluating and managing risks throughout the AI lifecycle.
These resources point toward a practical principle: the security of an agent depends on the controls surrounding it, not merely on the quality of the model's responses.
The model can improve. Its tools can become more capable. Its reasoning can become more sophisticated. The organization still needs to know what the system can access and what happens when it makes a bad decision.
There is a business problem hiding inside the security problem
At this point, some companies will respond by locking everything down.
No external access. No autonomous actions. No production integrations. Every tool call requires a human approval. Every experiment goes through a lengthy review.
Congratulations. You have built an extremely cautious AI system.
It’s also completely useless.
A customer-support agent that needs approval before every database lookup will struggle to deliver meaningful productivity improvements. An engineering agent that cannot inspect logs or execute tests will have limited value in diagnosing production problems. A financial operations agent that cannot submit an approved transaction may simply create more work for the employee who has to finish the process manually.
The business challenge is finding the right balance between autonomy and control.
A company wants its agents to handle routine work independently while escalating decisions that carry meaningful financial, legal, operational or security consequences.
That requires a clear understanding of which tasks can be automated, which permissions are necessary, what constitutes acceptable behavior and where human intervention should remain mandatory.
It also requires the ability to measure whether the system is delivering enough value to justify its operating cost and residual risk.
Consider a company that wants to automate invoice processing. Its agent might extract information from invoices, compare it with purchase orders, flag discrepancies and prepare payments.
The organization could permit the agent to process routine invoices below a defined threshold while requiring human approval for unusual amounts, new suppliers or changes to payment details.
The agent's effectiveness would then be measured through processing time, error rates, fraud exposure, exception handling and the amount of manual work eliminated.
Security, operational design and business economics are connected here. The company needs to understand both what it can safely delegate and what that delegation is actually worth.
This is where experienced engineering leaders like you can make a significant difference. They can work with security, product, finance and operations teams to design systems that deliver measurable results without giving autonomous software unrestricted authority.
The person who can explain that trade-off clearly to a CIO will have a much more useful conversation than someone who can only demonstrate an impressive model.
Why this could create interesting opportunities for technology leaders
Let's be clear about something: the OpenAI incidents do not prove that companies are suddenly going to hire thousands of dedicated AI-agent security engineers. Nor can we conclude from a handful of disclosures exactly how compensation or hiring demand will change.
What they do is make an increasingly important engineering problem visible.
As organizations connect autonomous systems to real infrastructure, they need people who understand how to deploy, secure, monitor and operate those systems.
That work draws on several existing disciplines, but it also creates new combinations of responsibilities.
Security leaders need to understand how agents interact with tools and data, how prompt injection can affect a workflow, and how to enforce security policies outside the model.
Infrastructure leaders need to understand isolation, workload identity, network boundaries, credential management and the operational consequences of granting an agent access to production systems.
Platform engineering leaders need to build environments where developers can deploy agents without reinventing security controls for every application.
Identity teams need to account for non-human actors that may operate across services, invoke other tools and act on behalf of employees.
And engineering executives need to bring all these capabilities together while keeping the business moving.
The five capabilities I would focus on
If you're a Senior Engineering Manager, Director, VP or CTO who wants to prepare for this market, I would concentrate on five areas.
1. Learn to design boundaries around autonomous systems
Understand how identity, authorization, isolation and tool access work together. Learn how to issue short-lived credentials, scope permissions to specific resources and prevent an agent from expanding its own authority.
You should be able to explain what happens when an agent attempts an action outside its approved scope. Does the infrastructure reject it? Is the attempt logged? Does anyone receive an alert? Can the agent continue working on other parts of the task without gaining additional privileges?
Study the practical guidance in the OWASP Agentic Applications framework and the Microsoft documentation on agent identity and least privilege.
You don't need to become a specialist in every security domain. You do need enough depth to make architectural decisions, challenge unsafe assumptions and work effectively with the people who own the controls.
2. Learn what happens after the demo
A model that performs well during a demonstration has not necessarily earned the right to run a business workflow autonomously.
Production systems need monitoring, evaluation, incident response, recovery mechanisms and clear ownership.
Suppose an agent helps engineers investigate production incidents. How will you measure whether its recommendations are correct? How will you identify a sudden increase in incorrect actions? What happens when the underlying model changes? Can you roll back a new version? What happens if an external API becomes unavailable halfway through a workflow?
And if the agent makes a mistake, can you reconstruct the sequence of decisions and tool calls that led to it?
These are familiar questions from distributed systems and production engineering, but agentic systems make them more complicated because the sequence of actions may vary between runs.
The leaders who can take a system from a promising prototype to a reliable production service will have a substantial advantage over those whose experience ends at the demonstration stage.
3. Understand the economics of AI infrastructure
Security and reliability are essential, but companies also need their AI investments to make economic sense.
Learn how inference costs, model selection, caching, latency, utilization and orchestration affect the cost of delivering a service. Understand when a smaller model is sufficient, when retrieval is preferable to fine-tuning and how a workflow's economics change when usage grows tenfold.
Then connect those technical decisions to the business.
If your platform supports hundreds of internal agents, a 25% reduction in operating costs could produce meaningful savings. If better evaluation reduces the number of expensive human reviews, you may improve both throughput and margins. If a reusable platform helps teams deploy new applications in weeks rather than months, that can change the economics of the entire AI program.
You should be able to explain the baseline, the improvement, the trade-offs and how the result was measured.
A technical accomplishment becomes a much stronger executive story when you can quantify its effect.
4. Become excellent at evaluation and observability
One of the most important questions in enterprise AI is surprisingly straightforward:
How do we know this system is actually working?
For a conventional application, teams can often test whether a request returned the expected result. AI systems may produce variable outputs, use different sequences of tools or encounter information that was not represented in the original test set.
You need representative evaluations, clearly defined success criteria and a way to measure behavior after deployment.
For an autonomous agent, that means evaluating the final outcome as well as the actions taken along the way. Did it complete the task? Did it access only the permitted information? Did it follow the required approval process? Did it create duplicate transactions? Did it escalate an uncertain decision appropriately?
You also need to monitor latency, costs, failure rates and unusual tool usage in production.
The strongest leaders will know how to turn these measurements into decisions about whether an agent is ready to launch, should receive more autonomy, needs a different architecture or should be taken offline.
5. Learn to explain the risk and value to executives
This is particularly important at Director, VP and C-suite level.
Your CEO does not need a twenty-minute explanation of every tool invocation. They need to understand what the system can do, why the business needs it, what could go wrong and what controls are in place.
Can you explain why an agent has access to a particular database? Can you show which actions require human approval? Can you describe the financial exposure if something goes wrong? Can you explain how the company would detect an incident and recover?
You should also be able to explain the upside in business terms.
Perhaps the agent reduces the time required to investigate customer complaints. Perhaps it allows a smaller operations team to handle a larger volume of transactions. Perhaps a shared platform reduces the time and cost required to deploy new AI applications.
A senior technology leader needs to understand both sides of that equation.
The goal is to give executives enough information to make informed decisions about investment, risk and operational responsibility.
The bigger opportunity is in enterprise AI that actually works
The security of autonomous agents is one example of a broader transition taking place in enterprise technology.
For several years, much of the attention surrounding AI has focused on model capabilities: better reasoning, longer context windows, multimodal inputs and increasingly sophisticated applications.
But the value a company captures also depends on the systems surrounding the model.
An enterprise still needs reliable data, integrations with existing software, appropriate permissions, usable interfaces, monitoring, cost controls and people who understand the business process being automated.
If any of those pieces are missing, a technically impressive model can still produce a disappointing product.
This is why I would encourage technology leaders to look beyond the latest model announcement and examine the engineering problems that appear when AI meets real infrastructure.
The NIST AI Risk Management Framework and its Generative AI Profile provide useful starting points for thinking about risk across the lifecycle of an AI system. OWASP's agentic security guidance offers a more focused view of risks associated with autonomous actions and tool use.
These frameworks are useful because they turn a vague discussion about AI safety into concrete engineering questions: What are the foreseeable failure modes? Who owns the risk? What evidence do we have that the controls work? How will the system be monitored after launch?
For a technology leader, answering those questions is a chance to develop expertise that connects architecture, security, operations and business strategy.
It also creates a much more durable career narrative than simply listing the models or frameworks you've worked with.
How to turn this into your next career move
Even if you are already doing this work, your experience will not automatically translate into a better opportunity. You need to be able to explain it in a way that makes its relevance obvious to another company.
Start by examining the projects you have owned over the last two or three years.
Which systems did you take into production? What decisions did you make about architecture, security or infrastructure? What problems did you solve? How did you measure the results? What changed for the business because of your work?
If you helped deploy an agent platform, describe its scale, the workflows it supports, the controls you introduced and the measurable results it produced.
If you led an infrastructure team, explain how you improved reliability, reduced costs or made it possible for other engineering teams to ship products faster.
If you worked in security, explain how you reduced exposure while allowing the business to deploy useful AI applications.
A hiring manager evaluating a Director or VP candidate wants to understand the scale of the problems you have handled and the level of judgment you exercised.
You should also pay attention to where companies are investing. Look at job descriptions, engineering leadership announcements, security initiatives and the technical problems organizations are trying to solve. Identify the capabilities that appear repeatedly, and work out how your experience maps to them.
If your current role gives you access to production AI systems, evaluation frameworks or platform security, seek responsibility for those areas. If you have been working exclusively on prototypes, look for an opportunity to own deployment, monitoring and operational outcomes.
And when you're ready to move, make sure your search is built around the roles where your experience has the strongest value. A generic résumé that says you have worked with AI will struggle to communicate the difference between someone who has experimented with a model and someone who has built the infrastructure that allows an enterprise to use it safely.
The question I would ask every technology leader
Imagine your company deploys an AI agent tomorrow. It can inspect internal systems, retrieve data, call APIs and take actions without asking a human to approve every step.
Your CIO asks you three questions.
What can this agent access?
How do we know it is behaving within its approved boundaries?
And what happens if it doesn't?
Can you answer those questions with a concrete architecture, measurable controls and a tested recovery plan?
If you can, you are solving a problem that matters to the business.
If you can also explain how the system creates value, what it costs to operate and how its success is measured, you are developing the kind of judgment companies need when moving AI from experimentation into production.
That is where I see a compelling career opportunity for experienced technology leaders.
The industry will continue to build more capable models. Companies will continue to look for ways to automate work and improve productivity. As those systems gain access to more of the real world, organizations will need people who can make them reliable, secure and economically useful.
Five years from now, a board might ask why an AI agent had access to a sensitive system.
The engineering leader who can explain the architecture, demonstrate the controls, show the audit trail and quantify the business value will be in a very different position from the person who can only explain how impressive the model was.
And that is the kind of expertise I would start building today.
Want us to run your search for you?
Book a free market audit call. We’ll review your positioning, assess your market and show you what it takes to land interviews.
Book a Free Market Audit →